Ready to start your journey as a Data Engineer? Learn industry-ready skills and build real-world data solutions. Grab now

Chennai: +91-9707250260 Bangalore: +91-8767260270 Online: +91-8099770770 Hire Talent (HR): +91-9707240250

Advanced Certification in Data Engineering

Ranked #1 Data Engineering Training Institute with Certifications.

Learn Data Engineering with key tools like Python, SQL, Apache Spark, and cloud platforms. Gain practical skills in data pipelines, ETL processes, data processing, and building reliable data systems.

  • Enroll Now for Trending Courses with Career Support
  • 16+ Years experience in Software Training & Placements
  • 20+ Branches in Chennai, Bangalore & Online

4.9 Ratings

10.3k Learners

Our Certificates

Earn valuable credentials and recognition

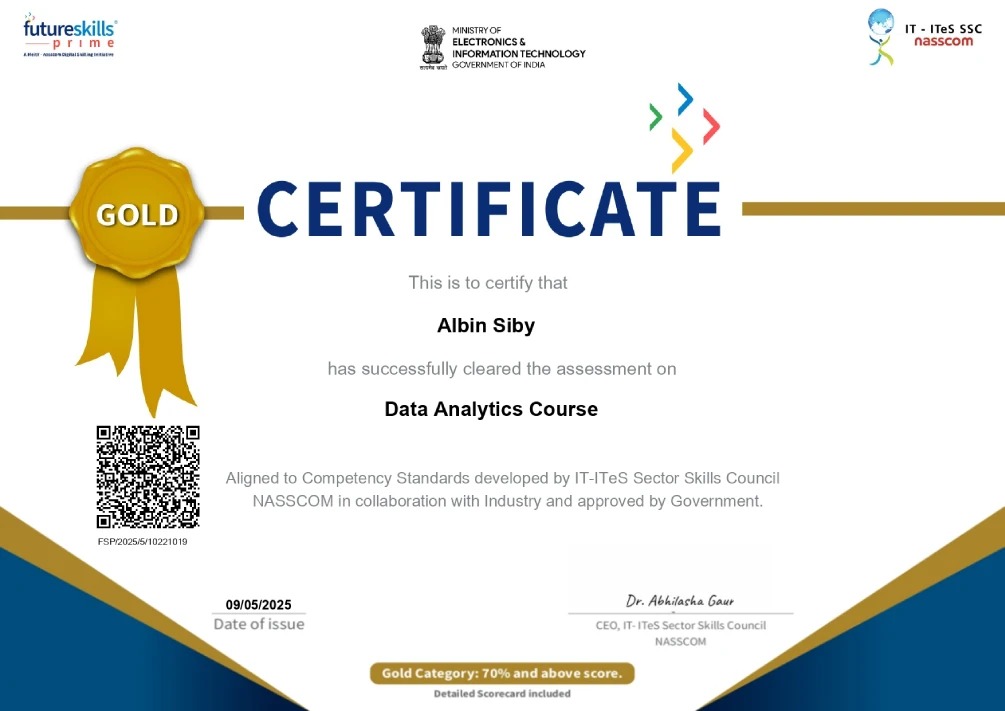
  • Earn Certification from NASSCOM Future Skills
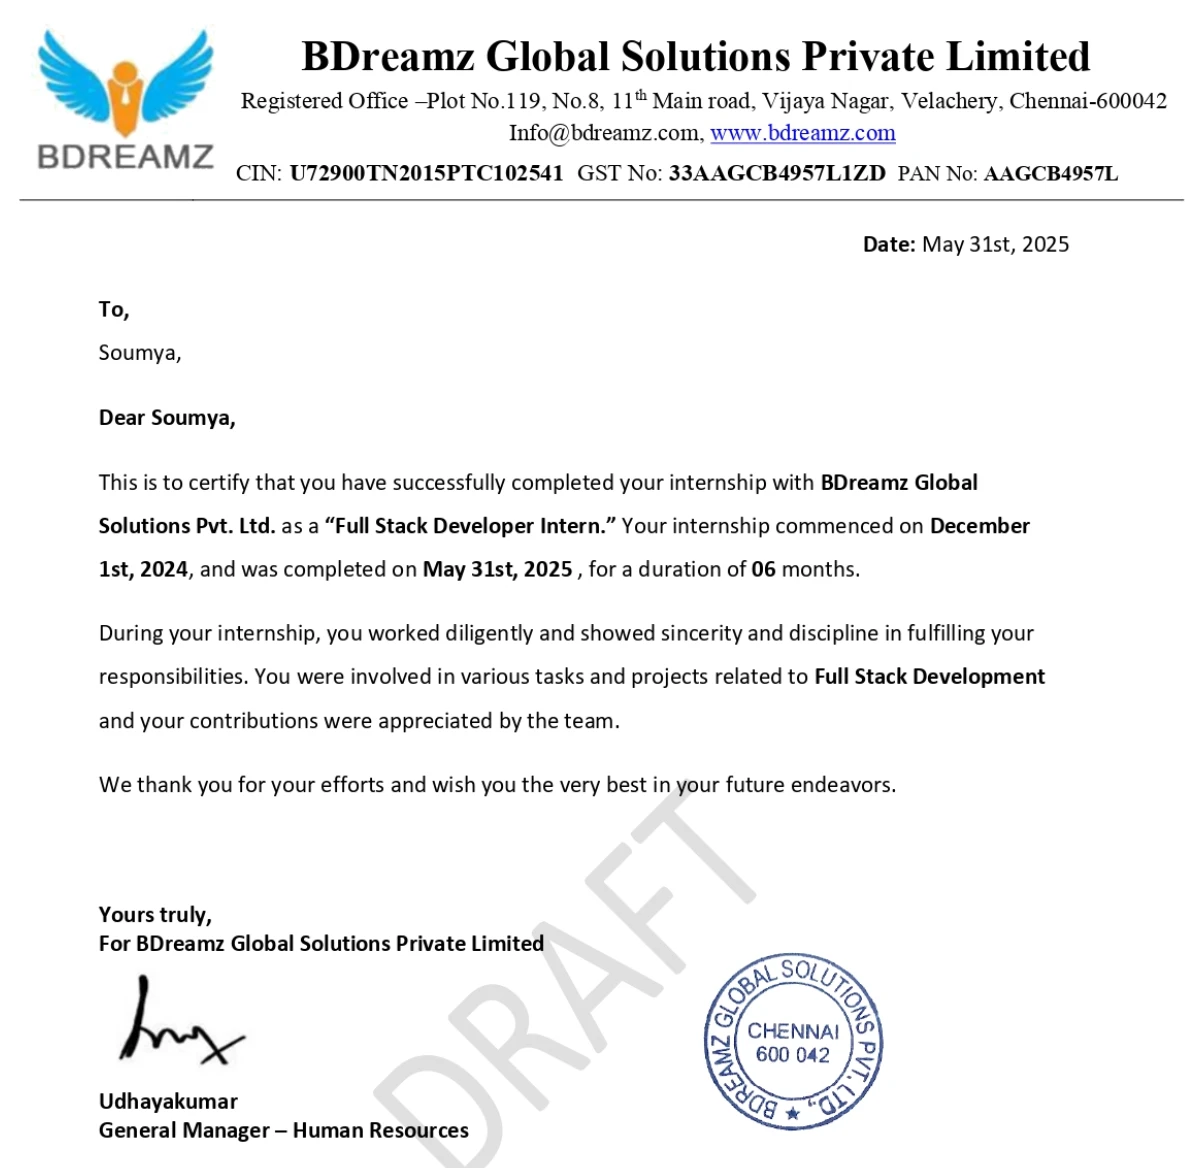
  • Six Months Internship Certificate
certificate NASSCOM Future Skills
Letter Letter for Internship Completion
certificate Course Completion Certificate
What you’ll learn

Program Highlights

Convenient learning format

Convenient learning format

Online Data Engineering training with guidance and support from experienced trainers.

Dedicated career services

Dedicated career services

Resume building and interview preparation with career guidance and job assistance.

Learn from the best

Learn from the best

Learn Data Engineering from experienced trainers with practical knowledge of modern data technologies.

Structured program with dedicated support

Structured program with dedicated support

A well-structured learning program with dedicated support to help you stay on track.

Hands on learning

Hands on learning

Build real-world Data Engineering projects and gain practical experience with Python, SQL, Azure, PySpark, Databricks, and other industry tools.

Data Engineering Course Content

Programming & Data Modeling

Module 1: Python for Data Engineering

  • Python Fundamentals — setup & environment, variables, data types, functions, modular code, loops, conditions, logic building
  • Data Structures — lists, tuples, sets, dictionaries, iteration techniques
  • Pandas & NumPy — Series & DataFrames, data reading/writing, cleaning, filtering, sorting, aggregation, numerical operations
  • Scripting & Automation — running scripts, best practices, reusable components

Module 2: Data Handling with Python

  • Working with Tabular Data — CSV, Excel, JSON, handling missing data, type conversions
  • Data Cleaning & Transformation — filtering, grouping, merging, joining, reshaping
  • Data Analysis Essentials — EDA, summary statistics, Matplotlib/Seaborn visualization

Module 3: SQL Fundamentals

  • SQL Basics — SELECT, WHERE, JOINs, filtering, sorting
  • Query Writing & Optimization — subqueries, indexing, execution plans
  • Database Design Fundamentals — normalization, keys, relationships
  • Hands-on Practice Exercises — real query-writing drills

Cloud & Security

Module 4: Cloud & Microsoft Azure Foundations

  • Cloud Fundamentals — cloud computing basics, public/private/hybrid models, use cases
  • Azure Fundamentals — navigating Azure Portal, key services overview
  • Cloud Service Models — IaaS, PaaS, SaaS with real-world examples
  • Azure Environment Setup — creating account, first resource group, hands-on launch

Module 5: Secure Identity & Access Management in Azure

  • IAM Fundamentals — identity & access management, authentication vs authorization
  • Microsoft Entra ID (Azure AD) — tenants, users, groups, roles, RBAC
  • SPN & Managed Identity — service principals, when to use which
  • Security Best Practices — secure access to storage, databases & services

Storage & Integration

Module 6: Azure Storage & Data Lake Fundamentals

  • Storage Fundamentals — storage account basics, architecture for data platforms
  • Blob Storage Essentials — containers, folder structures, block/append/page blobs
  • Advanced Storage Concepts — metadata storage, audit logs, configuration management
  • Queue Storage & Workflows — table storage, queue storage for DE workflows

Module 7: Azure Data Lake Storage Gen2 (ADLS Gen2)

  • ADLS Gen2 Overview — architecture, hierarchical namespace
  • Working with Data Lake — file systems, directories, files, configuration
  • Data Ingestion & Management — ingesting & accessing data
  • Data Lake Best Practices — design concepts, performance & cost optimization

Module 8: REST APIs & Data Integration Fundamentals

  • APIs Fundamentals — REST APIs in data engineering, REST vs SOAP
  • API Integration Concepts — real-world integration scenarios
  • Working with APIs — testing tools, CRUD operations
  • API Data Handling — extracting data, error management

Module 9: Azure Data Factory (ADF)

  • ADF Fundamentals — architecture & pipeline execution flow
  • Pipelines, Datasets & Integration Runtime — linked services, dataset types
  • Data Integration & Orchestration — connecting to Storage/SQL/REST, scheduling & triggers
  • Monitoring & Best Practices — debugging, optimization, production pipelines

Data Processing

Module 10: PySpark Foundations

  • Intro to Databricks & Spark — SparkSession, execution flow, transformations vs actions, lazy evaluation
  • Core Concepts & Data Structures — RDDs, DataFrames, Spark SQL
  • Data Ingestion in PySpark — CSV/JSON/Parquet, schema inference
  • Data Output in PySpark — DataFrame APIs, save modes, partitioning

Module 11: Data Processing with PySpark

  • Data Transformation & Analysis — joins, aggregations, cleaning, type conversions
  • Advanced Analytics with Spark SQL — window functions, complex queries
  • Performance Optimization — partitioning, shuffle, caching, persistence
  • Monitoring & Tuning — Spark UI, stages/tasks/executors, tuning best practices

Module 12: Databricks Platform, Delta Lake & Governance

  • Databricks Platform Essentials — architecture, workspace, notebooks, clusters
  • Data Connectivity & Storage — connecting to ADLS Gen2, mounting, secure access
  • Delta Lake Essentials — Delta architecture, Delta tables, ACID transactions
  • Governance & Unity Catalog — permissions, access control, data governance

Module 13: Databricks Lakehouse Architecture & Pipelines

  • Lakehouse & Medallion Architecture — Bronze/Silver/Gold, layered pipeline design
  • Building Data Pipelines — batch & real-time streaming pipelines
  • Advanced Pipeline Concepts — incremental processing, CDC
  • Use Cases & Best Practices — cost optimization, scalable pipelines

Microsoft Fabric

Module 14: Introduction to Microsoft Fabric

  • What is Microsoft Fabric — how it differs from Azure Data Engineering
  • Microsoft Fabric Components — unified platform for DE, DS & analytics
  • Real-time Analytics in Fabric — benefits for modern data engineering
  • Microsoft Fabric Eventhouse — real-time ingestion & processing

Module 15: Data Integration & Orchestration with Fabric

  • Dataflows Gen2 in Fabric — explore & integrate
  • Pipelines for Data Engineering — pipeline concepts & templates
  • Run & Monitor Pipelines — performance tracking
  • Real-time Data Processing — ingest, transform, store, query & visualize

Module 16: Lakehouse, Delta Tables & Warehousing in Fabric

  • Lakehouse & Medallion Architecture — Bronze/Silver/Gold in Fabric
  • Delta Tables in Fabric — creating & handling via Spark, structured streaming
  • Data Warehousing in Fabric — fact tables, dimensions, loading via T-SQL
  • Dataflows & Data Management — loading/transforming, managing & protecting data

Module 17: CI/CD, Deployment & Governance in Fabric

  • Data Loading & Pipeline Strategies — loading into Fabric Warehouse
  • CI/CD in Microsoft Fabric — Git version control, deployment pipelines
  • Automation with APIs & KQL — automating CI/CD tasks, KQL
  • Advanced SQL & Analytics — materialized views, stored functions

Snowflake

Module 18: Snowflake Fundamentals & Architecture

  • Snowflake Basics — use cases, why Snowflake for modern platforms
  • Setup & Environment — creating account, Web UI navigation
  • Architecture & Storage Layers — cloud services/compute/storage layers, micro-partitioning
  • Data Types & Tables — VARIANT type, permanent/temporary/transient tables

Module 19: Data Loading & Transformation in Snowflake

  • Data Loading Fundamentals — Time Travel, Fail-safe, Zero Copy Cloning
  • Stages & COPY Command — file formats, COPY command usage
  • Streams, Tasks & Automation — SQL for ETL, scheduling tasks
  • Real-time ETL & Integrations — Data Lake integration, BI tool connections

Module 20: Performance Optimization & Warehousing in Snowflake

  • Virtual Warehouses — sizing, auto-suspend/auto-resume
  • Performance Tuning — clustering keys, query profiling
  • Caching & Optimization — compute resource management
  • Schema Design & Best Practices — star vs snowflake schema, data modeling

Module 21: Security, Governance & Data Sharing in Snowflake

  • Authentication & Access Control — RBAC, sensitive data access
  • Security & Monitoring — encryption at rest/in transit, auditing
  • Data Sharing & Masking — secure data sharing feature
  • Governance Best Practices — compliance & operational best practices

Orchestration & Streaming

Module 22: Apache Airflow

  • Airflow Fundamentals — components overview
  • Installation & Setup — installing, Web UI
  • DAGs, Operators & Tasks — workflows & dependencies
  • Scheduling & Jobs — creating, triggering, monitoring jobs

Module 23: Apache Kafka

  • Kafka Fundamentals — need for Kafka, core concepts
  • Kafka Architecture — where it's used, cluster components
  • Kafka Cluster Management — brokers, topics, partitions, replication, producers/consumers
  • Reliability & Best Practices — high availability, fault tolerance

Capstone Project

Capstone Project

  • End-to-end Data Engineering project
  • Data ingestion and integration
  • Data transformation and processing
  • Data pipeline development
  • Cloud-based data engineering implementation
  • Data quality and validation
  • Pipeline monitoring and optimization
  • Project deployment and presentation

Electives

Module 24: Power BI & Business Intelligence

Duration: 30 hrs

  • Power BI Fundamentals — connecting to Azure / Snowflake / Databricks sources
  • Data Modeling & DAX Basics — relationships, calculated columns/measures
  • Building Dashboards & Reports — visuals, interactivity, drill-throughs
  • Row-Level Security & Publishing — securing & sharing reports

Module 25: DevOps

Duration: 30 hrs

  • CI/CD & Automation — build/release pipelines
  • Docker, Kubernetes & More — containerization basics
  • Infrastructure as Code — automated environment provisioning
  • Real-world DevOps Projects — applied practice

Do you like the curriculum?

Request Batch

You Always Get the Best Guidance

13K
Students Enrolled
20+
Overall Branches
9300+
Placed Students
16+
Years of Experience

Recommended Combo Courses

Azure

Azure Cloud

Rating 5.0 (1965)
Skill Level

Beginner

Hours

30

Learners

2360

Azure

Data Engineering

Rating 5.0 (1865)
Skill Level

Beginner

Hours

30

Learners

1989

Master the tools

Enroll Now

Trusted by 25 Million Happy Learners

Ready to Get the Best Data Engineering Training with Besant Technologies?

A Data Engineer plays an important role in every organization by building and managing data pipelines, databases, and data platforms that help businesses work with their data effectively. In India, Data Engineering is in high demand, with growing opportunities across IT, finance, healthcare, e-commerce, and other industries.

Get Started

Praise from a Happy Students

Frequently Asked Questions

Besant Technologies is a training institute offering a wide range of technology and professional courses. Our courses are designed to provide practical learning through instructor-led training, hands-on exercises, projects, and industry-relevant skills.

The Data Engineering course at Besant Technologies focuses on practical skills required to build, manage, and maintain modern data platforms and pipelines. The training covers Python, SQL, Microsoft Azure, Azure Data Factory, PySpark, Databricks, Microsoft Fabric, Snowflake, Apache Airflow, and Apache Kafka.

The Data Engineering course includes:
  • Hands-on learning with industry-relevant tools and technologies
  • Practical assignments and real-world data engineering exercises
  • Training on cloud-based data platforms and data pipelines
  • Capstone project experience to apply your learning

A basic understanding of programming, databases, or computer science can be helpful, but learners from different educational and professional backgrounds can join the course. An interest in Python, SQL, databases, and cloud technologies will be useful.

The Data Engineering training includes practical projects based on real-world data workflows. You will work on data ingestion, data transformation, data pipelines, cloud storage, data processing, and data integration. The capstone project gives you an opportunity to bring these concepts together and work on an end-to-end data engineering solution.

We offer Classroom Training and Online Training for the Data Engineering course. You can choose the training mode that best suits your learning requirements.

Yes, Besant Technologies provides job assistance to eligible learners. The support may include interview preparation, resume guidance, and assistance with job opportunities. The Data Engineering training helps you build practical skills that can be useful when applying for Data Engineer and related technology roles.

The Data Engineering course can be suitable for students, graduates, IT professionals, software developers, and professionals looking to build skills in data platforms and cloud technologies. The following learners may benefit from the training:

  • Fresh graduates interested in starting a career in Data Engineering
  • Software developers looking to move into Data Engineering
  • Database and SQL professionals
  • Data Analysts looking to learn data engineering skills
  • IT professionals interested in cloud and data platforms

The course completion certificate provided by Besant Technologies does not have an expiry date. It can be used as proof of completing the Data Engineering training and learning the covered concepts and technologies.

Besant Technologies follows its applicable refund and cancellation policy for course enrollments. Please check the current terms and conditions or contact the Besant Technologies team for details regarding your specific enrollment.

We accept multiple payment options, including cash, card, net banking, and available online payment methods. You can contact the Besant Technologies team for the currently available payment options.

What is Data Engineering?

Data Engineering is the process of collecting, storing, transforming, and managing data so that it can be used effectively for analytics, reporting, and business applications. Data Engineers build and maintain data pipelines, databases, and cloud-based data platforms.

What is the objective of the Data Engineering Course?

The Data Engineering course is designed to help you build practical skills for working with modern data platforms, data pipelines, cloud technologies, and large-scale data processing.

  • Learn Python and SQL for data processing, automation, and database operations.
  • Understand data ingestion, data transformation, data integration, and pipeline development.
  • Learn Microsoft Azure services such as Azure Data Factory and Azure Data Lake Storage Gen2.
  • Work with PySpark, Databricks, Delta Lake, and Lakehouse architecture for large-scale data processing.
  • Learn Microsoft Fabric, Snowflake, Apache Airflow, and Apache Kafka for modern data engineering workflows.
...

Prerequisites to Learn Data Engineering

The Data Engineering Course is suitable for students, graduates, software developers, data analysts, database professionals, and IT professionals who want to build skills in data engineering and cloud technologies. Basic knowledge of programming, databases, or SQL can be helpful.

  • Programming Knowledge: Basic understanding of programming concepts can help you learn Python, scripting, and data processing more easily.
  • Database Knowledge: Basic knowledge of SQL and databases is useful for working with data, queries, tables, and data warehouses.
  • Problem-Solving Skills: Logical thinking and an interest in working with data can help you understand data pipelines and solve data-related problems.

Skills Covered in Data Engineering Course

  • Python
  • SQL
  • Data Cleaning & Transformation
  • Data Pipelines
  • Microsoft Azure
  • Azure Data Factory
  • Azure Data Lake Storage Gen2
  • PySpark
  • Databricks
  • Delta Lake
  • Microsoft Fabric
  • Snowflake
  • Apache Airflow
  • Apache Kafka
  • Data Warehousing
  • Cloud Data Engineering

What are the Benefits of Data Engineering Courses?

Data Engineering plays an important role in helping organizations collect, process, store, and manage large volumes of data. A Data Engineering course helps you develop practical skills to work with modern data platforms and build reliable data workflows.

  • It helps you build and manage data pipelines that move data from different sources into storage and analytics platforms.
  • It helps organizations process and organize large amounts of data for reporting, analytics, and business applications.
  • It provides practical knowledge of cloud platforms, data warehouses, data lakes, and modern data processing technologies.
  • It helps you work with technologies such as Azure, Databricks, Snowflake, Microsoft Fabric, PySpark, Airflow, and Kafka.

Our Branches

Data Engineering, Get practical training for a high-paying career.

Download Brouchure